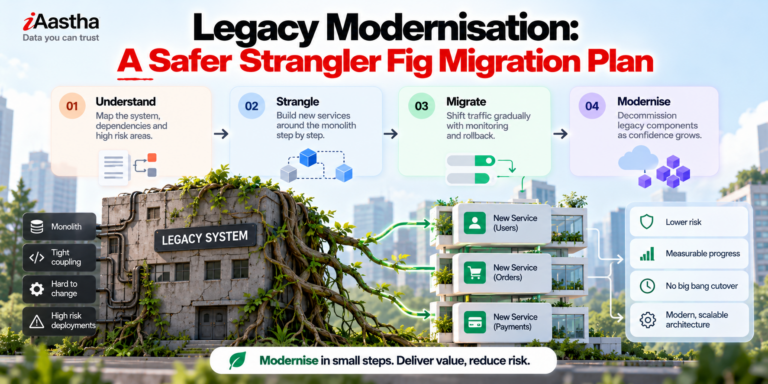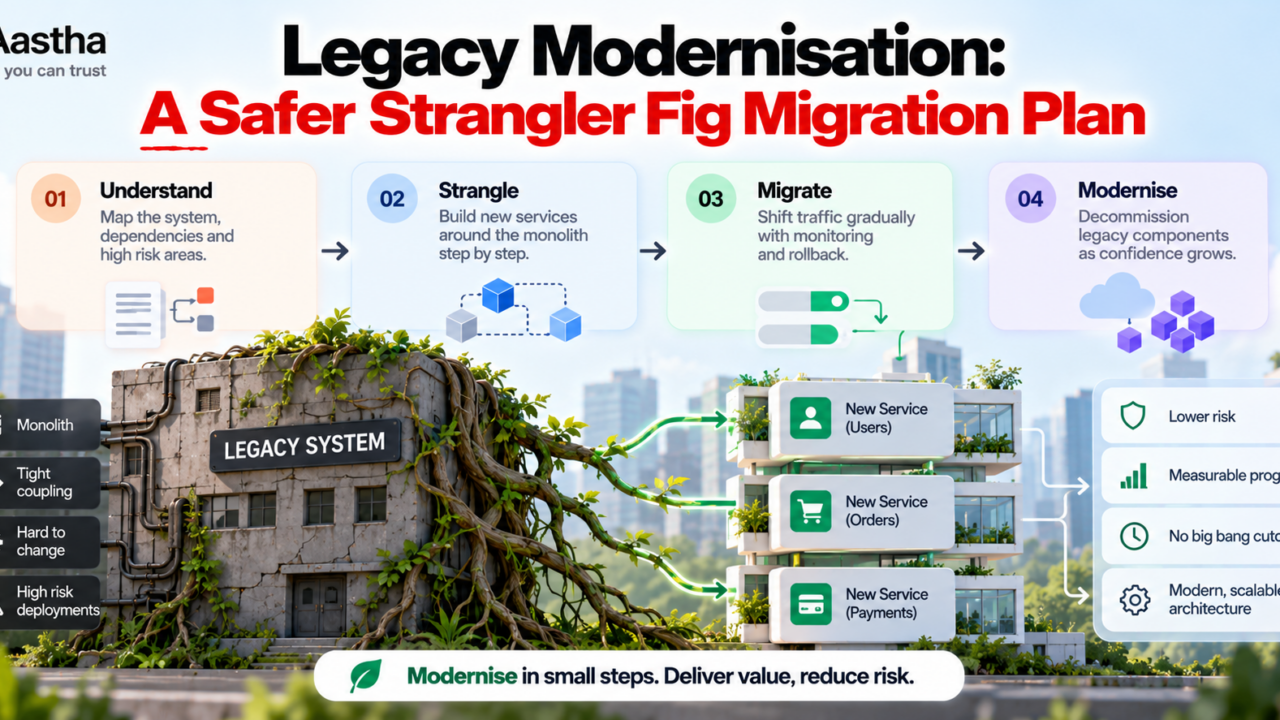
- Legacy modernization is safest when you replace one business capability at a time, not the whole system at once.
- The strangler fig pattern places a routing layer in front of the old system so new code can take over gradually.
- Trust comes from evidence. Compare old and new behavior on real traffic before you move customers.
- The migration is only finished when the old path is deleted.
Most legacy modernisation programs do not fail because the new technology is bad. They fail because the plan asks the business to trust one big switch that nobody can test. Incremental legacy modernisation removes that bet. You move one business capability, prove it works, and only then move the next.
This guide uses a hypothetical account-notification service to explain boundaries, coexistence, traffic routing, behaviour comparison and the retirement of the old path. You can try a routing simulator and a readiness checklist as you read.
What is the strangler fig pattern?
The strangler fig pattern is a legacy system migration strategy in which you build new functionality around the edges of an old system and gradually route work to it, until the old system can be switched off. Martin Fowler popularized the name. It comes from strangler figs, vines that grow around a host tree and slowly replace it.
In practice, the strangler fig pattern for microservices teams is simple. Put a facade or proxy in front of the legacy application. Carve out one capability and rebuild it as a new service. Let the facade decide, request by request, which path answers.
Why incremental beats a big bang rewrite
A full rewrite delivers nothing until it delivers everything. Meanwhile the old system keeps changing, so the target keeps moving. Incremental legacy application modernization strategies avoid that trap.
| Big bang rewrite | Incremental (strangler fig) | |
| Risk | Concentrated in one cutover | Spread across small, reversible steps |
| Feedback | Arrives at the end | Arrives with every capability |
| Rollback | Hard or impossible | A routing change |
| Business value | Delayed until launch | Delivered capability by capability |
Our example: a hypothetical account-notification service
Imagine an enterprise platform built around a twenty-year-old monolith. Inside it sits an account-notification module. It sends emails and texts when a password changes, a new device signs in or a payment fails. Other modules call it directly, it reads customer data from the shared database, and nobody remembers every rule it applies.
This example is invented, but the shape is common. Notifications make a good first capability: they are visible and valuable, and a mistake has a smaller blast radius than it would in billing or identity.
Step 1: Draw the boundary
Define the capability by the business outcome it owns. Here that outcome is: tell the customer when something important happens to their account. Everything the capability needs to deliver that outcome belongs inside the boundary.
Inventory the real behavior
List the inputs (account events), the outputs (messages and delivery status) and the data owned (templates, preferences, send log). Then look for the quiet rules: quiet hours, duplicate suppression, regional legal footers. Document the contract the old module actually follows, not the one in the wiki.
Find the hidden couplings
Search for every caller and every table the module touches. Direct method calls and shared tables are the usual surprises. Each one is a seam you will need to replace with an event or an API.
Step 2: Let old and new coexist
For a long time, both paths will be alive. Design for that on purpose, because coexistence is where most migration incidents happen.
Put a routing layer in front
Add a facade, gateway or proxy that receives every notification request. At first it forwards everything to the old module. The old path stays the default, and the new service earns each increment of traffic.
Decide who owns the data
Avoid two writers for the same data. Prefer a single source of truth and let the new service consume events instead of reading the old tables. If you must synchronize, make the direction explicit and monitor for drift.
Step 3: Route traffic gradually
Traffic routing is where the strangler fig pattern becomes real. You do not flip a switch. You move a controlled share of requests, watch what happens, and move the dial again. Drag the slider to see how each stage changes.
Try it: split traffic between old and new
Share of live requests handled by the new service: 0%
Old: 1000 per 1,000New: 0 per 1,000
Shadow mode. The old path answers every request. The new service gets a copy, and you compare its output without sending anything to customers.
Step 4: Compare behavior before you trust it
Shadow mode is the safest way to start. The old path still answers every request. The new service receives a copy, and you record what it would have done without sending it to a customer.
For notifications, compare the template chosen, the recipient, the channel, the timing and the suppression decision. Sort every difference into one of three groups: a bug in the new service, a bug in the old one (decide whether to preserve or fix it), or an acceptable difference.
Write the exit criteria before you start. For example: no unexplained differences across a full business cycle, including month-end and billing runs. Evidence beats confidence, and a written threshold keeps the decision honest.
Step 5: Retire the old path
A migration that leaves the old path alive creates a second system to maintain. Set a retirement date at the start, and treat the end of the project as deletion, not cutover.
Remove the routing rule and the feature flags. Delete the old module, its scheduled jobs and its unused tables. Update runbooks and dashboards, archive the logs you must keep, and confirm that no caller still depends on the old interface. Then pick the next capability and repeat.
Check your readiness
Tick what is true for your team today.
Is your first capability ready to migrate?
We can name the business outcome this capability owns.
We have listed every caller and every shared data store.
A routing layer can split traffic by request or customer segment.
We can return to the old path in minutes.
We wrote exit criteria for comparing old and new behavior.
A named owner and a date exist for retiring the old path.
0 of 6 ready. Not yet. Close the gaps above before you route any live traffic.
Common mistakes to avoid
- Starting with the hardest capability instead of a valuable, contained one.
- Sharing the legacy database indefinitely.
- Skipping comparison because the new code seems obviously better.
- Leaving the retirement date undefined.
- Treating modernization as an IT-only project, without business owners.
Frequently asked questions
What is legacy modernization?
Legacy modernization is the process of updating or replacing older software so it is easier to change, run and secure, while the business keeps operating. Approaches range from rehosting to full replacement.
What is the strangler fig pattern in microservices?
It is an approach where a routing layer sits in front of a legacy application and sends selected requests to new microservices. Over time the new services handle more work until the old system is removed.
How long does incremental legacy modernization take?
There is no honest universal number. Each capability takes as long as its size and coupling require, and the program continues until every capability is moved. The benefit is that value arrives with each slice instead of at the end.
What is the best legacy system migration strategy?
For systems that must keep running, an incremental strategy such as the strangler fig pattern is usually the safest. A full rewrite can make sense only for small, well-understood systems.
When should you avoid the strangler fig pattern?
Avoid it when you cannot intercept requests at any boundary, or when the system is small enough to replace safely in one step.