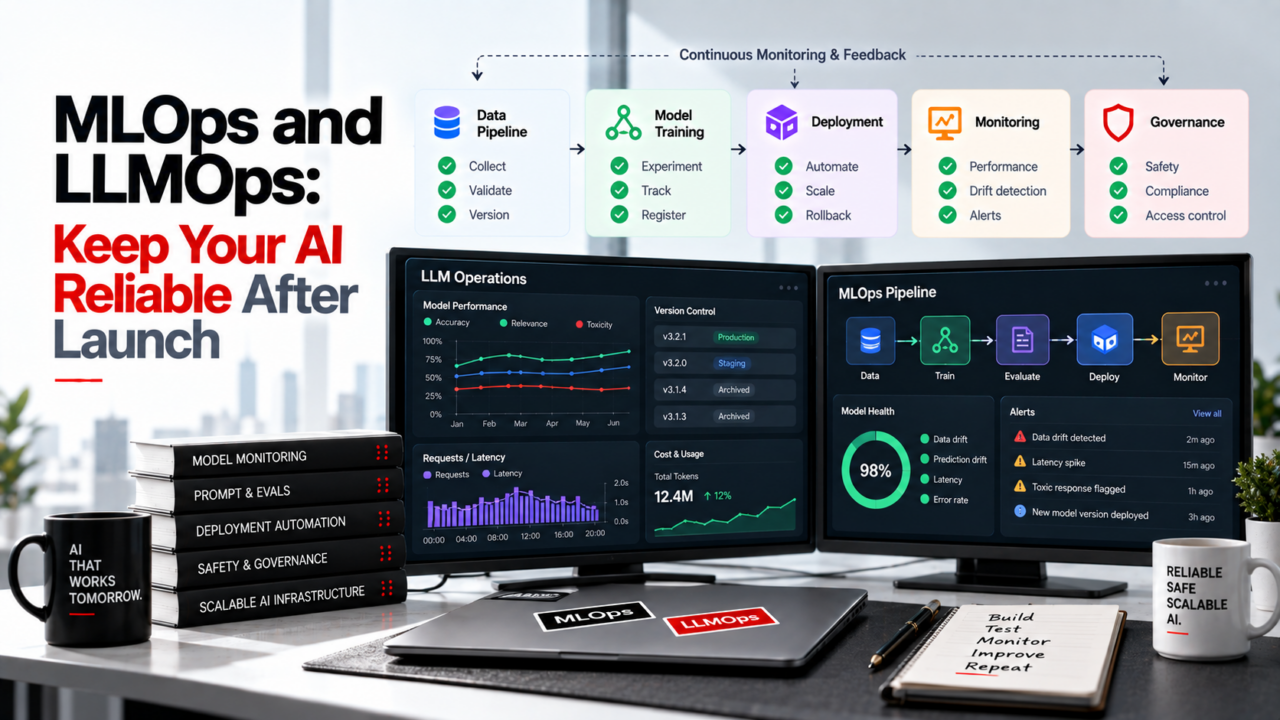
MLOps and LLMOps are the monitoring, evaluation, versioning and governance practices that keep AI systems accurate, safe and accountable after go-live. Models drift, prompts regress and costs creep. The fix is a simple loop: instrument every call, evaluate quality on a schedule, and release every change through a versioned, reversible path.
What are MLOps and LLMOps?
MLOps is the set of practices for running machine learning models reliably in production: tracking data and model versions, monitoring predictions, retraining when needed and controlling releases. LLMOps applies the same discipline to applications built on large language models, where the moving parts also include prompts, retrieval pipelines, tools and agent behaviour.
Both exist because of one uncomfortable fact. A model that passed its launch review is not automatically accurate a quarter later. The data changes, the users change, the upstream model provider updates a version, and someone edits a prompt on a Friday afternoon. Without operations discipline, nobody can tell which behaviour moved or when.
Why AI systems fail quietly after launch
Traditional software fails loudly. A server crashes, an error page appears, an alert fires. AI systems fail quietly. They keep returning answers that look plausible, so the damage shows up late: a recommendation engine slowly loses relevance, a support assistant starts giving outdated policy answers, or a scoring model treats a new customer segment unfairly.
Researchers at Google described this years ago in their well known paper on hidden technical debt in machine learning systems (Sculley et al., NeurIPS 2015). Their central point still holds: the model code is a small part of a production ML system, and most of the risk lives in the surrounding data, configuration and monitoring. LLM applications make that even more true, because the “code” now includes natural language instructions that anyone can edit.
Three failure patterns show up again and again:
- Drift: the live data no longer looks like the data the model learned from.
- Regression: a prompt, model or dataset change improves one behaviour and silently breaks another.
- Workarounds: users stop trusting the output and quietly build manual checks around it, which erases the value you built the system for.
MLOps vs LLMOps: what actually changes?
If you are wondering about the difference between MLOps and LLMOps, the short version is that the principles stay the same while the artifacts change. Here is a side by side view.
| Area | MLOps | LLMOps |
| What you version | Models, features, training data | Prompts, models, retrieval indexes, tools, datasets |
| Main risk | Data and concept drift | Prompt regression, hallucination, cost spikes |
| Evaluation | Accuracy, precision, recall on labelled data | Graded test sets, rubric scoring, human review |
| Cost driver | Training and serving compute | Tokens per call, context length, retries |
| Rollback unit | Model version | Prompt plus model plus config bundle |
How to monitor LLM models in production
Monitoring starts with a record. If you cannot reconstruct what the system saw and said, you can only guess at why it misbehaved. We treat this as step one of our approach: every prediction leaves a record.
What to log on every call
Capture the input, the output, the model and prompt version, the retrieved context if any, latency, token usage and cost. Add a trace ID so a single user complaint can be traced to the exact call. Mask personal data at the point of logging, not later.
What to track over time
Watch quality scores, refusal and fallback rates, latency percentiles, cost per request and the share of outputs flagged by users or reviewers. A single dashboard that shows these by version makes it obvious when a change helped or hurt.
Model drift detection in production
Drift comes in two main forms, and they need different checks.
Data drift
The inputs change. A lending model trained on salaried applicants starts seeing gig workers. Compare live feature distributions against a baseline window using tests such as the Population Stability Index (PSI) or the Kolmogorov-Smirnov test, and alert when the gap crosses a threshold you agreed in advance.
Concept drift
The relationship between inputs and the right answer changes. Customer behaviour shifts after a price change or a market event. This is harder to see because inputs may look normal. You catch it by tracking accuracy against fresh labels as they arrive, even if the labels are delayed by weeks.
For LLM applications, add a third lens: behavioural drift. Run the same fixed test questions every day and watch whether answers change after a provider model update.
Building an LLM evaluation framework for production
Quality has to be checked on a schedule, not when someone remembers. A workable evaluation setup has four layers:
- Regression suite: a fixed set of inputs with expected behaviour, run on every change.
- Graded evaluation sets: curated examples scored against a clear rubric for accuracy, tone, safety and groundedness.
- Online checks: sampling of live traffic, scored automatically.
- Human review: kept wherever automated scoring cannot be trusted, such as legal, medical or high value financial answers.
Using one model to grade another (often called LLM as judge) is useful for scale, but it needs calibration. Compare its scores to human ratings on a sample and revisit that comparison whenever the judge model changes.
Expert insight: The Sculley et al. paper makes the case that ML systems accrue maintenance cost faster than ordinary software because of data dependencies and feedback loops. That is the core reason evaluation and monitoring must be treated as permanent work, not launch work.
Prompt versioning best practices (and model and dataset versioning)
Our rule is simple: nothing changes without a version. That covers models, prompts, datasets and policies, and all of them move through the same gated release path.
- Store prompts in source control, not in a dashboard text box.
- Give every prompt, model and dataset an immutable version ID, and log it with each call.
- Require evaluation results to pass before a version is promoted.
- Record who approved the change and why, so audits take minutes rather than weeks.
How to roll back a bad model release
Rollback only works if you planned for it. Keep the previous version deployable, release new versions to a small share of traffic first (a canary), and define the trigger in advance: for example, a drop in quality score or a spike in cost beyond an agreed limit. Because prompt, model and configuration are versioned together, reverting is a switch, not a rebuild.
Frequently asked questions
What is the difference between MLOps and LLMOps?
MLOps operates predictive models trained on your data. LLMOps operates language model applications, where prompts, retrieval, tools and outputs also need versioning, evaluation and cost control.
How do you monitor LLM models in production?
Log every call with inputs, outputs, versions and cost, then run scheduled evaluations on graded test sets and track quality, latency, cost and failure rates over time.
How do you detect model drift in production?
Compare live input and prediction distributions against a baseline using tests such as PSI or Kolmogorov-Smirnov, and track accuracy against fresh labels when they arrive.
When should we start MLOps?
Before launch. Instrumentation and versioning are far cheaper to build in than to retrofit once users depend on the system.
Do we need MLOps consulting in India or can we build it in house?
Many teams build the basics in house and bring in a partner for evaluation design, governance and audit readiness. iAastha works from Indore and Mumbai with startups, enterprises and GCCs.
Conclusion
A model in production is a system to be operated. The work that matters most starts at launch: evaluation that keeps running, versioning that makes every change reversible, and monitoring that tells you which behaviour moved and when. Teams that build this discipline early spend less time firefighting and more time improving.
Explore our MLOps & LLMOps service or write to business@iaastha.com.